<style>
#doc.markdown-body,#doc.markdown-body .markdown-body{max-width:980px;margin:0 auto;color:#28252a;background:#fcfaf7;font:17px/1.65 -apple-system,BlinkMacSystemFont,"Segoe UI",sans-serif}
#doc.markdown-body{padding:0 28px 80px}#doc.markdown-body a{color:#9b2854;text-underline-offset:3px}#doc.markdown-body h1,#doc.markdown-body h2,#doc.markdown-body h3{color:#211721;letter-spacing:-.02em}#doc.markdown-body h2{margin-top:64px;padding-top:18px;border-top:1px solid #e9e2e3}#doc.markdown-body table{width:100%;border-collapse:collapse;margin:24px 0}#doc.markdown-body th{text-align:left;background:#f2e8ed}#doc.markdown-body td,#doc.markdown-body th{padding:12px 14px;border-bottom:1px solid #e9e2e3;vertical-align:top}#doc.markdown-body img{max-width:100%;height:auto}
.abx-header{box-sizing:border-box;display:flex;align-items:center;justify-content:space-between;gap:24px;width:100%;margin:24px 0 28px;padding:15px max(24px,calc((100% - 1280px)/2));border-bottom:1px solid #e9e2e3;background:#fcfaf7;color:#28252a;font:14px/1.5 -apple-system,BlinkMacSystemFont,"Segoe UI",sans-serif}.abx-header a{text-decoration:none}.abx-header .abx-brand{display:inline-flex;align-items:center;gap:11px;color:inherit;font-size:19px;font-weight:750;line-height:1.2;white-space:nowrap}.abx-header .abx-subsite{margin-left:2px;color:#716c74;font-size:12px;font-weight:450}.abx-header .abx-nav{display:flex;align-items:center;justify-content:flex-end;flex-wrap:wrap;gap:0;font-size:13px;font-weight:600}.abx-nav>a,.abx-nav>details{margin-left:15px;padding-left:15px;border-left:1px solid #ded4d8}.abx-nav>:first-child{margin-left:0;padding-left:0;border-left:0}.abx-header .abx-nav a{display:inline-flex;align-items:center;min-height:36px;color:#4d424b;white-space:nowrap}.abx-header .abx-nav a:hover{color:#9b2854}.abx-apps>summary{display:flex;align-items:center;gap:7px;min-height:36px;list-style:none;cursor:pointer;color:#4d424b}.abx-apps>summary::-webkit-details-marker{display:none}.abx-apps>summary:before{content:'›';color:#9b2854;font-size:22px}.abx-app-links{position:absolute;right:0;top:calc(100% + 12px);z-index:5;width:260px;padding:8px;border:1px solid #e9e2e3;border-radius:16px;background:#fcfaf7;box-shadow:0 18px 48px #2d152522}.abx-app-links a{display:flex;align-items:center;gap:8px;padding:8px}.abx-app-links img{object-fit:contain;flex:0 0 auto}.abx-cta{margin-left:18px;padding:9px 17px;border:1px solid #9b2854;border-radius:24px;background:#9b2854;color:#fff!important}@media(max-width:700px){#doc.markdown-body{padding:0 16px 56px;font-size:16px}.abx-header{display:block;padding:14px 18px}.abx-nav{justify-content:flex-start!important;margin-top:8px}.abx-app-links{position:fixed;left:20px;right:auto;top:64px}}
</style>
<header class="abx-header" aria-label="ArchiveBox navigation"><a class="abx-brand" href="https://archivebox.io/"><img class="abx-logo" src="https://archivebox.io/assets/icon.png" alt="ArchiveBox" width="32" height="32"><span>ArchiveBox</span><span class="abx-subsite">Blog</span></a><nav class="abx-nav" aria-label="Main navigation"><a href="https://app.archivebox.io/">Apps</a><a href="https://github.com/ArchiveBox/ArchiveBox/wiki">Docs</a><a href="https://github.com/ArchiveBox/ArchiveBox">GitHub ↗</a><a class="abx-cta" href="https://archivebox.io/#install">Get started</a></nav></header>
# ArchiveBox v0.9 is now released. 🎉
It's been a long time since our last major release back in 2024!
Thanks for hanging in there, but I promise this release was worth the wait!
**[↗️ ArchiveBox 0.9](https://archivebox.io)** brings an entirely new archiving engine, massive performance & stability gains, UI improvements, all-new mobile & desktop apps, and 50+ new plugins.
> *We want all interactions with our UI to feel instant, regardless of collection size.*
> We're aiming for almost all features in the apps **respond to user actions in <=100ms.**
> <small>(when served on a 4GPU 4GB VPS with 1M snapshots in its DB)</small>
All of this while remaining 100% free, open source, and available across more platforms than ever.
> 0 analytics. 0 data collection.
> (Seriously, I have no idea how many of you there even are still using ArchiveBox!)
<img style="width: 10%" src="https://docs.monadical.com/uploads/c9600e1b-4270-4b03-a5ee-ae2baae6fe93.png"/>
<img style="width: 30%" src="https://docs.monadical.com/uploads/712023f5-d3ae-476e-a6c9-cd6770bb951e.png"/>
<img style="width: 30%" src="https://docs.monadical.com/uploads/0206a20e-e6a5-4945-b8f8-5974c9e36acf.png"/>
<img style="width: 30%" src="https://docs.monadical.com/uploads/ff5a0056-bda0-49b1-83f4-c1de1b4a719d.png"/>
## ✨ The big changes
- 📱 **NEW Native Mobile & Desktop Apps:** [iPhone](https://app.archivebox.io/) / [iPad](https://app.archivebox.io/) / [Android](https://android.archivebox.io/) | [macOS](https://app.archivebox.io/) / [Windows](https://electron.archivebox.io/) / [Linux](https://electron.archivebox.io/)
- 🗂️ **Redesigned output viewers:** beautiful new viewers for article text, extracted video/audio, metadata + more
- 🧭 **Vastly improved browser extension:** import bookmarks/history, uploads local screenshot & MHTML
- 🐘 **PostgreSQL support:** SQLite remains the default, but we caved to demand and finally added PostgreSQL
- 🗓️ **Scheduled crawls in the UI:** schedule recurring import jobs directly from the UI, all in one Docker container
- 👤 **Personas:** archive sites logged-in using cookies & settings synced from extension, CDP, or local browsers
- 🤖 **AI Tools:** new MCP server, SKILL.md, and built-in agent (opencode) that can handle custom archiving tasks
- 🔏 **Bulletproof chain-of-custody:** new merkle hashes, TLSNotary attestation, and OpenTimestamps integration
- ⬇️ **A new standalone oneshot CLI:** `abx-dl` uses the same plugins without needing a full ArchiveBox server
## 📱 Save from your phone. Browse from your desktop.
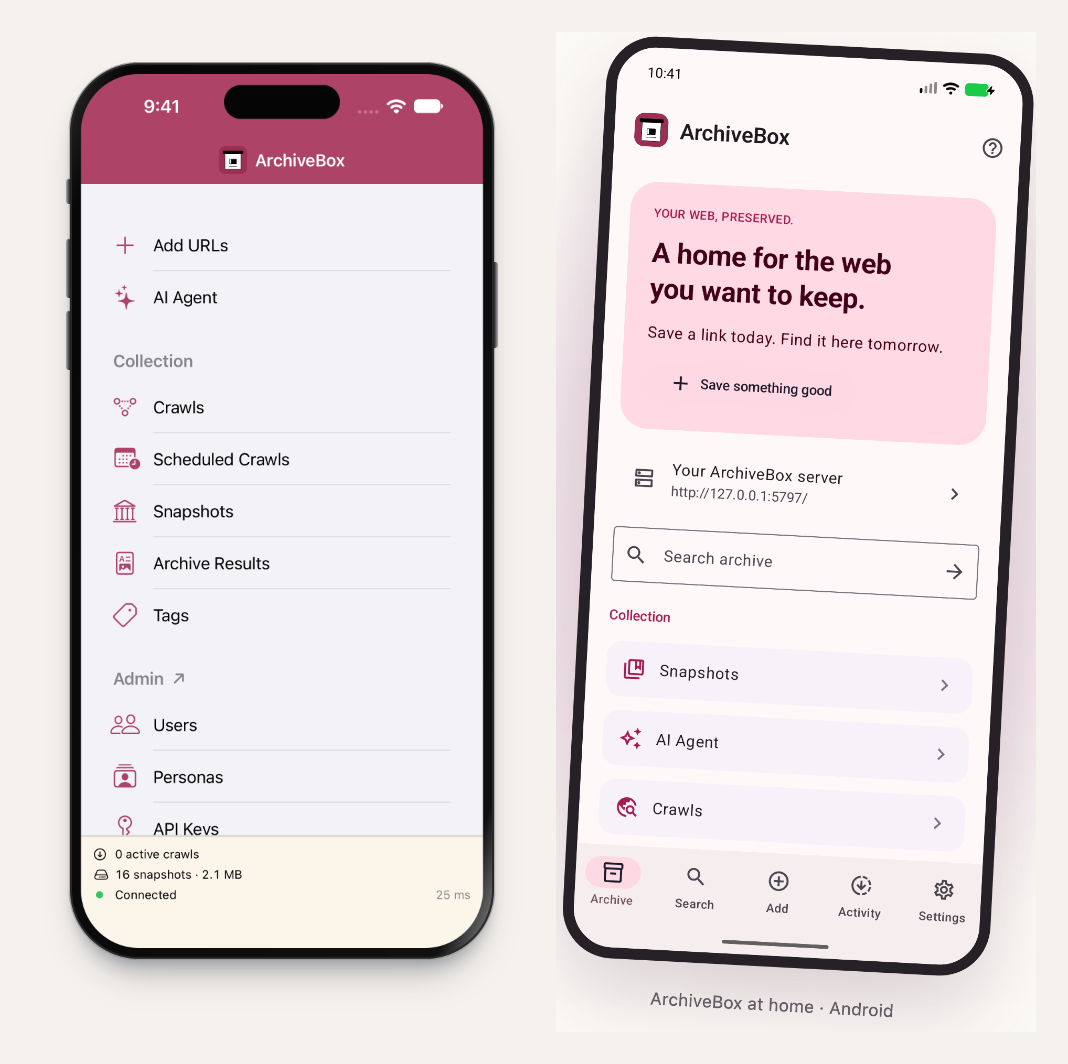
- **The phone apps connect to a server:** your Mac, home server, VPS, or another reachable ArchiveBox instance.
- **LAN / Tailscale discovery + connection QR codes** make setup easier. Access still depends on your network and authentication.
- **Close the desktop window without stopping the archive:** the server can keep working in the background.
- **Apple clients are beta; Android is available as a beta APK.** Check the app pages for current builds, OS requirements, and distribution channels.
[Apple apps](https://app.archivebox.io/) · [Android](https://android.archivebox.io/) · [Windows / Linux](https://electron.archivebox.io/)
## 🧭 Save pages exactly as you see them in your browser
- **Save one tab or a batch of URLs** from Chrome, Brave, Edge, Firefox, and supported mobile browsers.
- **Safari extension included with ArchiveBox.app**, including Safari on iOS.
- **Import bookmarks and browser history**, including Safari exports.
- **Automatically save matching URLs** using allowlists and denylists.
- **Capture locally and send to your server**, with supported formats varying by browser.
- **Keep browser cookies in sync with a server Persona** so captures can reuse your signed-in sessions.
- **Choose how long to keep local copies**, including deleting them shortly after successful server submission.
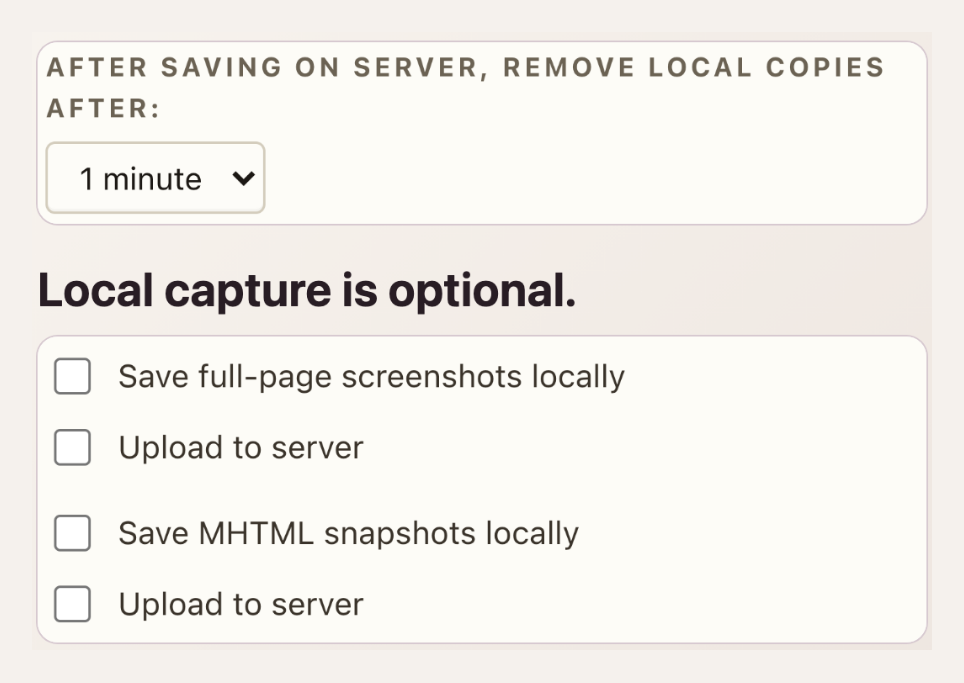
Local retention controls manage extension copies; they do not erase browser history or every trace of a visit. Cookie syncing is optional and gives the selected server access to those sessions.
[Get the browser extension](https://extension.archivebox.io/)
## 📡 See what the archive is doing
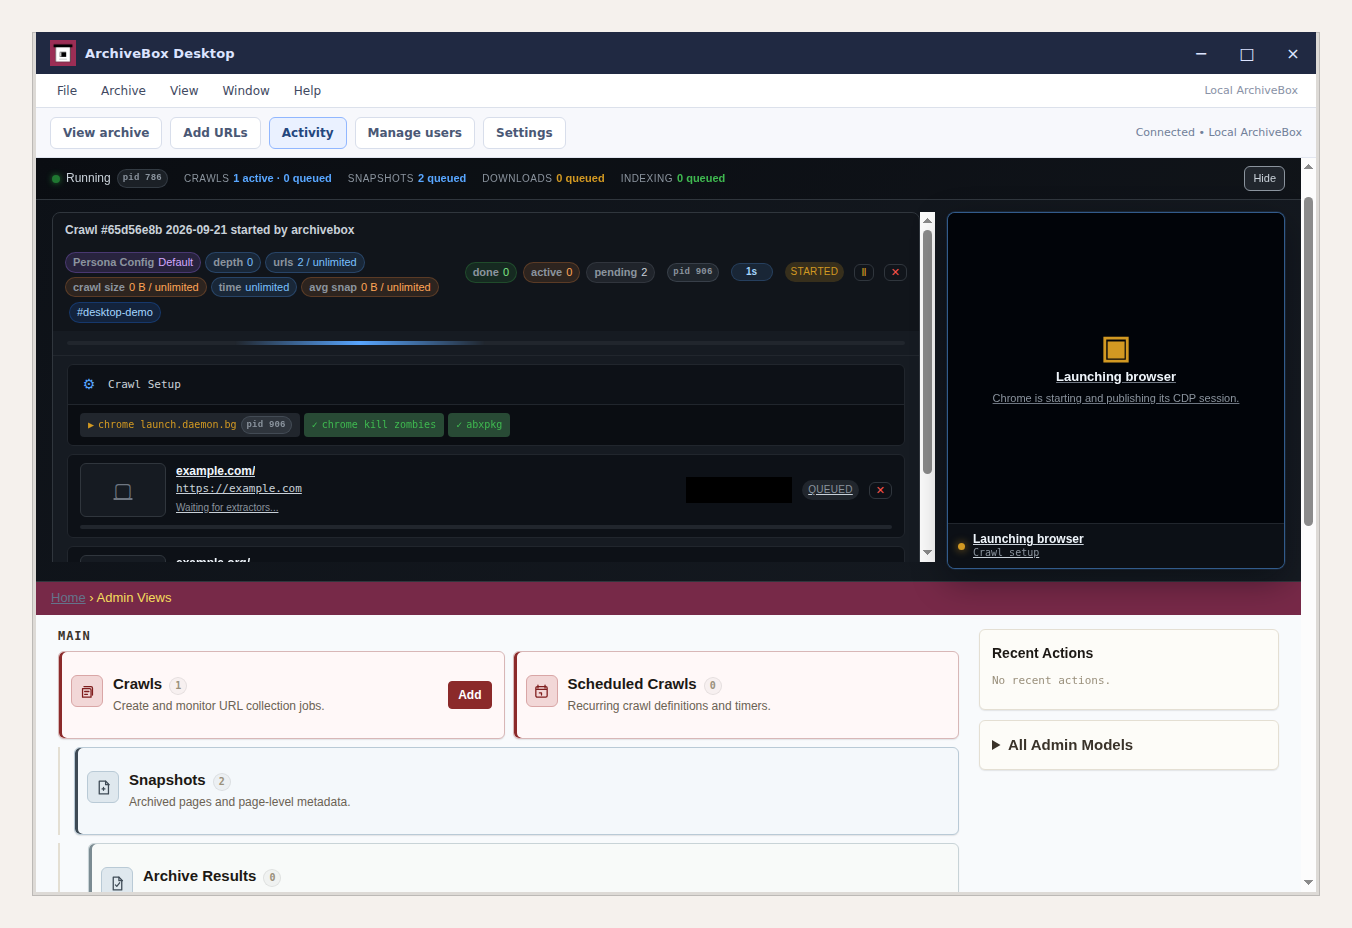
- **Live progress per crawl, page, and extractor.** Less guessing whether a job is stuck or still working.
- **Pause, resume, retry, and stop crawls** from the UI.
- **Recover queued work after restarts**, with one active orchestrator coordinating a collection.
- **Bound crawl depth, URL count, runtime, and size.** Keep a recursive crawl from taking over your machine.
- **Resource-aware admission:** hold back new work when CPU or memory is under pressure.
- **Prioritize newly submitted work** while a larger queue is still draining.
- **Inspect logs and failures** alongside the affected capture.
## 🗓️ Keep collections up to date
- **[Recurring crawls and imports](https://github.com/ArchiveBox/ArchiveBox/blob/dev/docs/Scheduled-Archiving.md) are managed in the web UI.** No separate cron sidecar required for the built-in scheduler.
- **Import RSS feeds, bookmark exports, and URL lists.** The Add URLs form can also read URLs from a local file.
- **User RSS feeds expose what a collection is saving.** Subscribe from another ArchiveBox instance to build shared or redundant archives.
- **Use per-crawl settings and Personas** instead of changing the defaults for your whole collection.
## 👤 Archive pages that need a login
- **Named Personas** keep browser profiles, cookies, and capture settings together.
- **Import a Chrome-based profile** and choose it for the relevant crawl.
- **Sync cookies from the browser extension** as your normal browsing session changes.
- **Keep crawl browser sessions separate**, with better cleanup of tabs and processes.
- **Reuse authenticated sessions** for the sites you already have access to: private documents, dashboards, social sites, and more.
Sites can still expire sessions or block automated access. Personas let you supply the right session; they don't bypass access controls.
## 🗂️ More useful saved pages
- **Responsive layouts** across phone, tablet, and desktop.
- **Expandable output stacks** group related capture formats together.
- **Article and document readers** for extracted text, including PDF extraction outputs.
- **Media galleries and players** for images, audio, video, and captured browser responses.
- **Repository previews** with a file browser and rendered README.
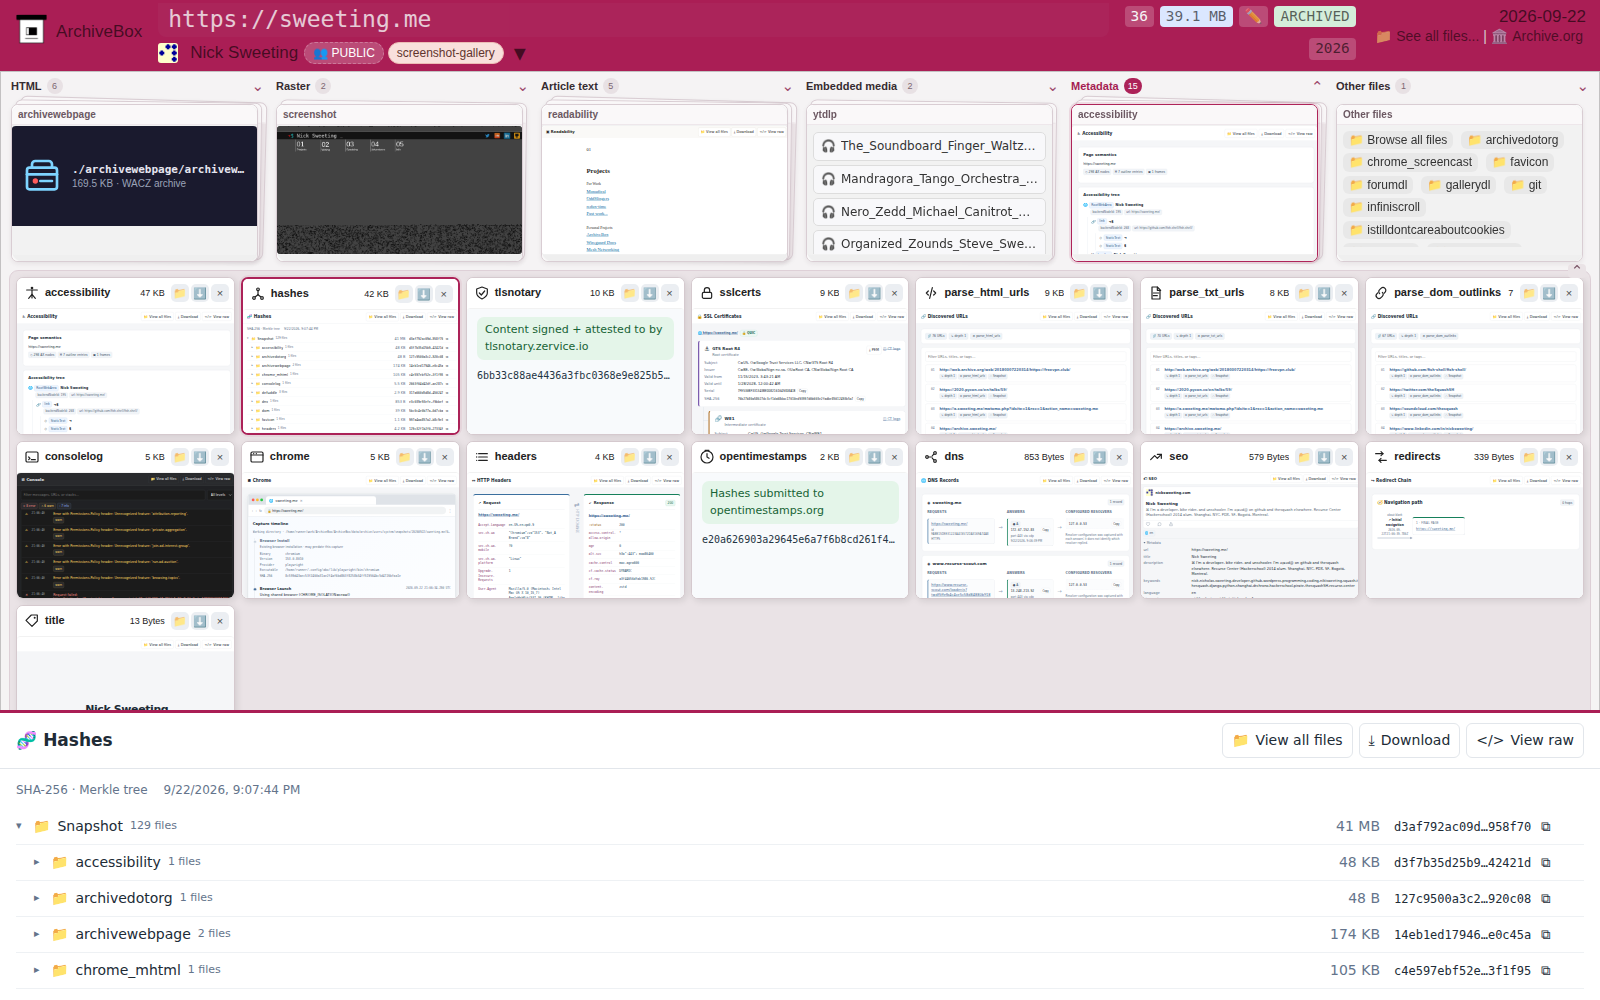
- **Readable metadata views:** redirects, headers, DNS, certificates, accessibility trees, browser activity, and console logs.
- **View raw, download one output, browse all files, or download a snapshot ZIP.**
## 🔎 [Find things again](https://github.com/ArchiveBox/ArchiveBox/blob/dev/docs/Setting-up-Search.md)
- Search **titles, URLs, tags, and captured text**.
- Choose **SQLite full-text search, Sonic, or ripgrep** for your deployment.
- **Streaming results and improved indexing** make large collections more practical to browse.
- Filter and organize snapshots without opening each saved page.
[Explore the real screenshot gallery](https://archivebox.io/screenshots/)
## 🧩 A much larger capture toolbox
The existing HTML, SingleFile, PDF, screenshot, article-text, Git, and media captures are still here. The 0.9 plugin system adds more capture options and makes them easier to combine.
| Capture | New and expanded options |
| --- | --- |
| **Interactive pages** | [ArchiveWeb.page](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/archivewebpage) / WACZ capture and replay, [Chrome MHTML](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/chrome_mhtml), captured network responses. |
| **Articles & documents** | [Defuddle](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/defuddle), [Trafilatura](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/trafilatura), [LiteParse](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/liteparse), and [OpenDataLoader](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/opendataloader) alongside existing text extractors. |
| **Media & discussions** | [GalleryDL](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/gallerydl), [ForumDL](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/forumdl), [PapersDL](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/papersdl), and updated [yt-dlp](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/ytdlp) integration. |
| **Browser context** | Redirects, DNS, TLS certificates, accessibility, console logs, and browser session metadata. |
| **Page interactions** | Optional scrolling, cookie-banner handling, modal removal, ad blocking, and configured CAPTCHA services. |
| **Integrity & evidence** | [File hashes](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/hashes), a Merkle tree, [TLSNotary](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/tlsnotary) attestations, and [OpenTimestamps](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/opentimestamps) proofs. |
- **Select plugins per crawl** and configure their limits.
- **Install dependencies through ArchiveBox**, instead of manually tracking every executable.
- **Write your own executable hooks** using the published plugin contract.
- **Keep each plugin's files in its own directory**, with structured result metadata.
[Browse the plugin library](https://plugins.archivebox.io/)
## 🤖 Ask an agent to work with your archive
- **Optional built-in OpenCode UI:** use your preferred configured model provider.
- **MCP server:** let an external agent add URLs, search captures, and manage collection records.
- **SKILL.md instructions:** give coding agents the CLI and filesystem context they need.
- **Use the agent for practical tasks:** choosing capture plugins, setting up a crawl, finding saved material, or investigating failed captures.
```ini
OPENCODE_ENABLED=True
```
Configure the model provider in the OpenCode settings after enabling it. Agent features are optional; ArchiveBox does not require an AI subscription to archive pages.
[OpenCode plugin](https://github.com/ArchiveBox/abx-plugins/tree/main/abx_plugins/plugins/opencode) · [MCP setup](https://github.com/ArchiveBox/ArchiveBox/tree/dev/archivebox/mcp)
## 🔏 Keep evidence you can check later
| Tool | What it adds |
| --- | --- |
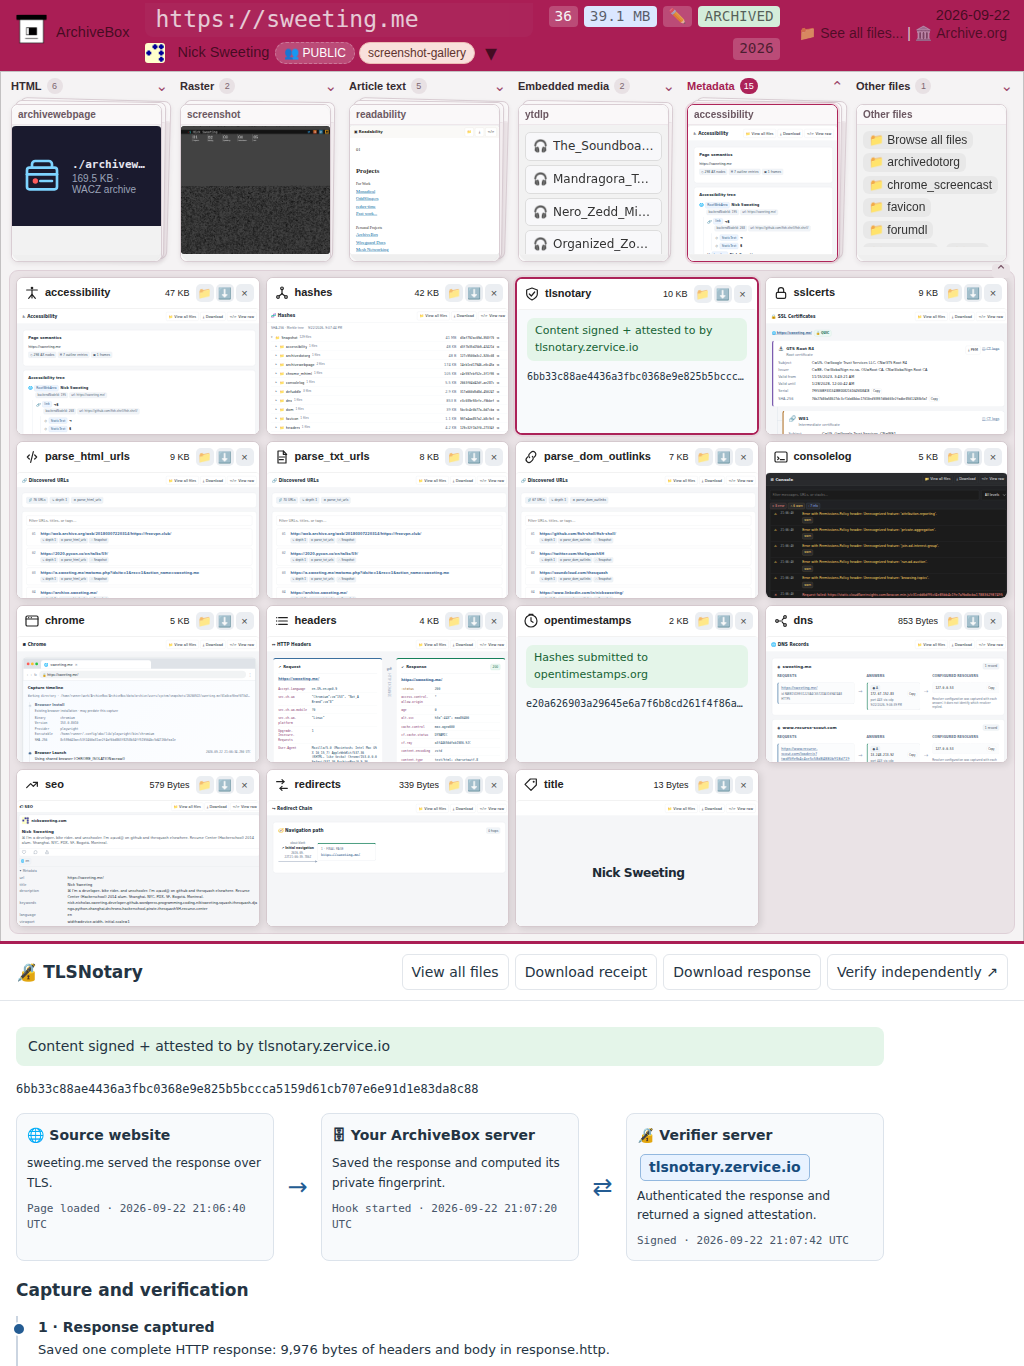
| **Hashes** | Full sha256 merkle tree hashing all the archived snapshot output when it's sealed. |
| **TLSNotary** | An optional verifier server witnesses a TLS response without needing the private page body or cookies revealed to it. Allows for anonymous, secure 3rd-party attestation. |
| **OpenTimestamps** | Store a merkle hash+salt of all the archived content at a point in time. |
[How the evidence fits together](https://tlsnotary.zervice.io/)
## 🛡️ [Better security isolation between the app and untrusted archived content](https://github.com/ArchiveBox/ArchiveBox/blob/dev/docs/Security-Overview.md)
- **Public, unlisted, and private snapshots**, with permissions checked on replay and API access.
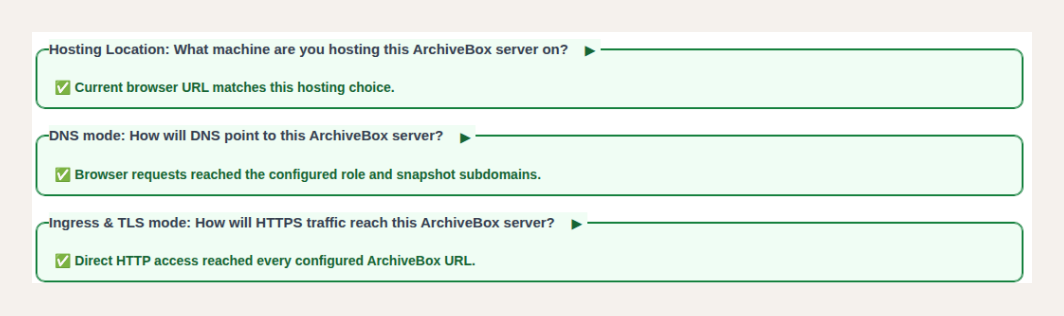
- **Separate admin, API, web, and snapshot origins** in the isolated replay configuration.
- **Script-disabled replay for ordinary single-domain setups.** Full archived JavaScript replay uses the appropriate isolated-host configuration.
- **Hardened cookies, CSRF checks, redirects, uploads, and webhook handling.**
## 🛠️ More ways to automate it
- **Expanded REST API** for crawls, snapshots, results, tags, users, tokens, and operational state.
- **Pipeable JSONL CLI commands** to create, read, update, delete, and enqueue model records.
- **Webhooks** for integrating archive events with other systems.
- **Standalone `abx-dl`** for one-shot downloads using the same plugin library, without a collection database or web server.
```bash
# Download a URL into files using the standalone tool
uvx abx-dl 'https://example.com'
# Find queued snapshots as structured records
archivebox snapshot list --status=queued
# Feed a crawl into snapshot creation and the runner
archivebox crawl create https://example.com \
| archivebox snapshot create \
| archivebox run
```
[abx-dl](https://github.com/ArchiveBox/abx-dl) · [ArchiveBox API](https://github.com/ArchiveBox/ArchiveBox/tree/dev/archivebox/api)
## ⬆️ Upgrading from 0.7.x
**Make a full offsite backup of your archive before proceeding, and be aware 0.9 will move some data/ dir files to new filesystem locations.** Filesystem migration is done lazily, and can be interrupted / resumed at will.
1. **Stop the old server.** `docker compose down`
2. **Back up the entire collection:** database, configuration, archive files, and browser Personas. A database-only backup isn't enough.
3. **Install 0.9.x following the instructions for your platform.** See https://archivebox.io
4. **Run `archivebox init` to upgrade the database.** Migrations can take minutes to hours depending on db size.
5. Run `archivebox update --migrate-only` to start migrating filesystem data to the new locations (if this step is skipped, it will happen lazily on first access and may slow down the UI)
6. **Keep the backup until you've verified the final setup looks good!**
For Docker Compose, **update your [`docker-compose.yml`](https://docker-compose.archivebox.io) first**, then:
```bash
docker compose run archivebox init
docker compose run archivebox update --migrate-only
docker compose down --remove-orphans
docker compose up -d
```
### Upgrade Notes
- We now recommend >= `2GB` RAM minimum, though it does still work (slowly) on smaller systems.
- **Custom config should be moved out of `docker-compose.yml` `environment:` into `data/ArchiveBox.conf`:** otherwise you wont be able to edit it via the new built-in Machine config admin UI
- **Python >=3.13+** is now required if installing on bare metal.
- **New filesystem layout** for `data/archive/` snapshot directories. Files will get auto-migrated on first access.
`data/archive/{timestamp}` -> `data/archive/users/{username}/snapshots/YYYYMMDD/example.com/{uuid}`
- **New DNS, SSL, and HTTPS serving requirements:** For better security, wildcard subdomain support was added to isolate archived JS, but new DNS+TLS settings are needed ([`BASE_URL`](https://github.com/ArchiveBox/ArchiveBox/wiki/Configuration#base_url) + [`SERVER_SECURITY_MODE`](https://github.com/ArchiveBox/ArchiveBox/wiki/Configuration#server_security_mode)).
- **[PostgreSQL support is added](https://github.com/ArchiveBox/ArchiveBox/wiki/Configuration#database_engine)**, ask your agent to help migrating data from SQLite if desired.
[Upgrade guide](https://github.com/ArchiveBox/ArchiveBox/wiki/Upgrading) · [Merging collections](https://github.com/ArchiveBox/ArchiveBox/blob/dev/docs/Merging-Collections.md) · [🐛 Report an issue](https://github.com/ArchiveBox/ArchiveBox/issues/new/choose)
## 🌱 Looking back since our last announcement
A lot of what we promised in [The Future of ArchiveBox](https://docs.monadical.com/archivebox-plugin-ecosystem-announcement) is now here:
- **The plugin ecosystem:** a separate [plugin library](https://plugins.archivebox.io/), more specialized downloaders, executable hooks, and automatic dependency installation.
- **The one-shot CLI:** [abx-dl](https://github.com/ArchiveBox/abx-dl) is now its own tool, using the same capture plugins as the server.
- **APIs and automation:** the expanded REST API, webhooks, scheduled crawls, and optional agents turn more of those proposed integrations into practical workflows.
- **More control over private archives:** Personas, browser session sync, snapshot permissions, and isolated replay give you more control over how logged-in captures are made and shared.
The architecture has changed along the way.
*The beginnings of P2P support are now here too* ✨, it's a little janky but I'm curious to hear if anyone starts doing it manually before I add official server-to-server linking.
---
> #### Tip: You can make one ArchiveBox server "follow" another server 🏛️ 🤝 🏛️
>
> 1. **On Server A:** Get your user's new snapshot feed as an RSS URL
`Admin > Auth > Users > RSS Feed > Right Click > Copy Url`
<img src="https://docs.monadical.com/uploads/13cfdeaf-a48e-44ce-a3bd-786e9d288f1a.png" width="200px"/>
> 2. **On Server B:** paste the RSS URL into the big URLs field on the `/add/` page,
set `depth=1`, set it up as a daily scheduled crawl, and submit.
> **Server B will now continuously watch for new URLs from Server A and archive them.**
---
### 📚 Further Reading
- [**The Scraping-With-Cookies Dilemma**](https://docs.sweeting.me/s/cookie-dilemma) explains why archiving logged-in content is hard to do securely, and why you cant share those archives easily without pwning your cookies & PII.
- [**Private Set Intersection for Web Content Anonymization**](https://github.com/pirate/html-private-set-intersection) explores comparing independently captured pages without exchanging their full contents. It's a proof of concept for how we aim to solve this between linked servers in the future.
- [**TLS-N: Non-repudiation over TLS**](https://eprint.iacr.org/2017/578) explains the new ZK-proof math that powers ArchiveBox's new 3rd-party signature+attestation system for verifiable archives
## 🙌 Thank you
Thanks to everyone who contributed code, tested migrations, reported broken captures, and helped improve the security of archived-page replay. This release includes work across the server, plugins, apps, extension, packaging, and documentation.
<details>
<summary><strong>🙌 Contributors and reporters</strong></summary>
Thank you to everyone who contributed code, documentation, testing, bug reports, and responsible security reports during the long road from 0.7.x to 0.9.x.
**Code and documentation contributors**
Sorted approximately by the size and quantity of accepted contributions:
@Brandl, @jimwins, @benmuth, @FellowTraveler, @pcrockett, @tqobqbq, @pellaeon, @sclu1034, @vladimirdulov, @andrew-d, @n-hebert, @gnattu, @danielalanbates, @boehs, @pyrox0, @ckiee, @neel-suthar, @dicnunz, @zkksdk, @1over137, @agowa, @benharri, @ckcr4lyf, @jasongodev, @naoph, @rdela, @slmingol, @ssoel, @TrisSherliker, @NelsonMinar, and @mpgirro.
**Issue reporters whose reports led to fixes**
This list excludes people already credited above for accepted code or documentation:
@amy-r-oss, @saiarcot895, @cyberproaustin, @BenCzaczkes, @larsony99, @tztzz, @JitteryDoodle, @Finkregh, @philippemilink, @sbutcher, @melyux, @m0nhawk, @danst0, @KagurazakaShirosatosu, @s7x, @mawmawmawm, and @cdzombak.
**Security researchers**
@DavidCarliez, @FUNFACTOR1, @g4nkd, @geo-chen, @iaohkut-from-NightWolf-Team, and @Vasco0x4.
</details>
[Full source comparison since 0.7.4](https://github.com/ArchiveBox/ArchiveBox/compare/v0.7.4...dev) · [Releases](https://github.com/ArchiveBox/ArchiveBox/releases) · [Support ArchiveBox](https://github.com/sponsors/pirate)